

Reinforcement Learning
6 related stories
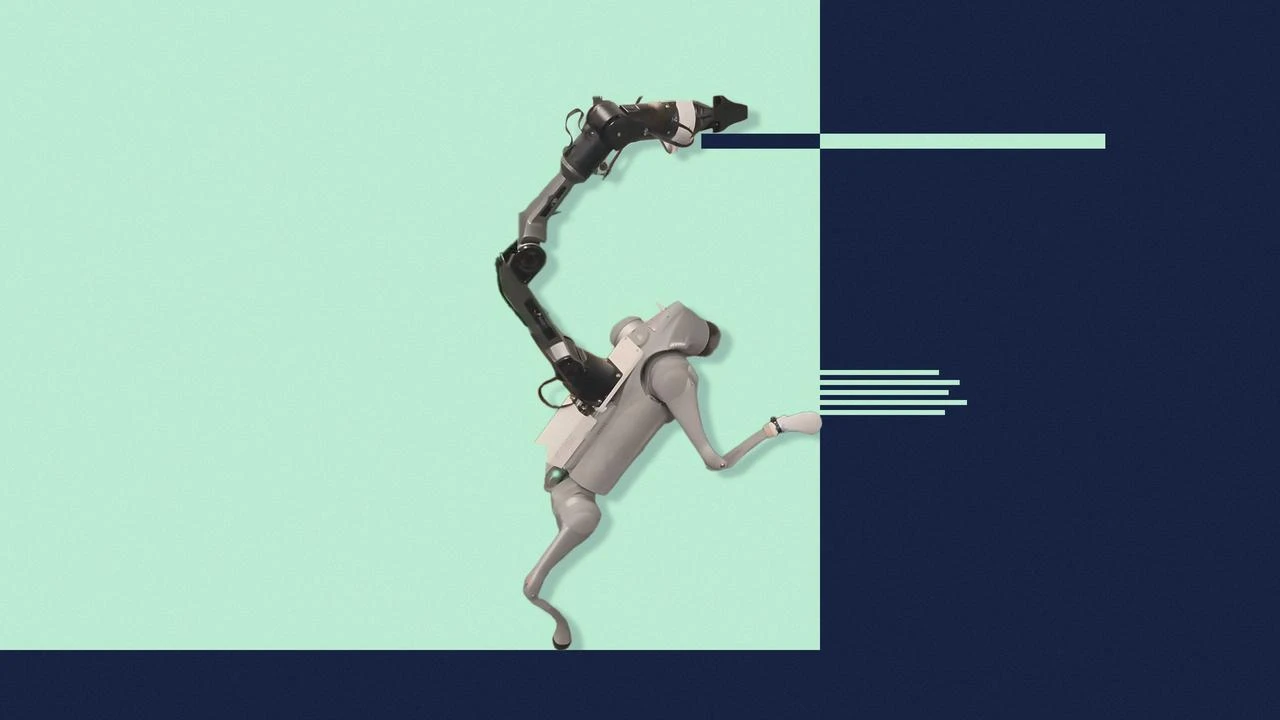
Carnegie Mellon Researchers Introduce ELEVATE Framework to Help Quadrupeds Acquire New Controllers from Task Failures
Quadruped robots with manipulators face a hard limit when required motions are absent from pre-trained libraries. The new ELEVATE framework enables these robots to autonomously diagnose missing physical capabilities during task failures and train new whole-body controllers using reinforcement learning.
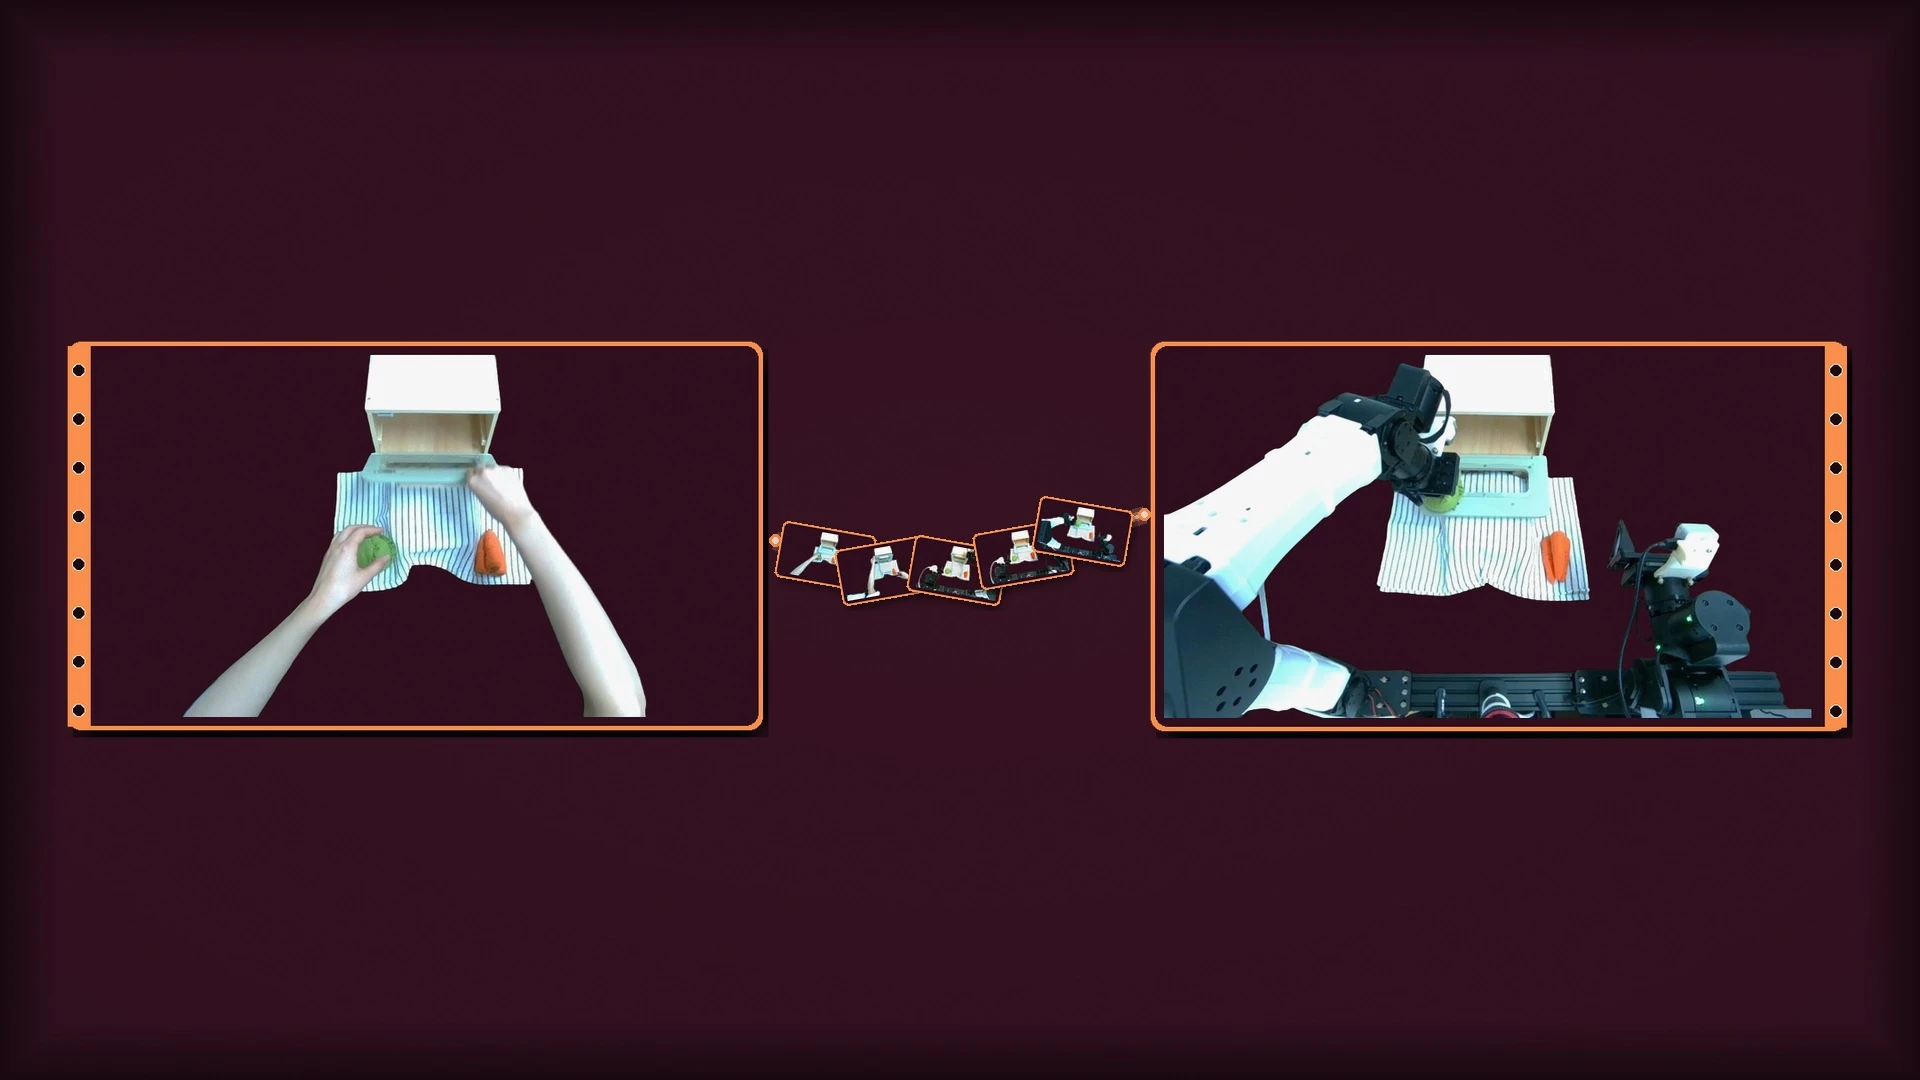
NVIDIA Proposes ThinkWorld to Train VLAs on Unannotated Human Videos via Chain-of-Dynamics and Imagined Futures
NVIDIA and KAIST introduce ThinkWorld, a vision-language action framework that leverages chain-of-dynamics reasoning and imagined future states to extract training signals from unannotated human videos for robot policy learning.
UC Berkeley's SuperMimic Slashes Compute for Humanoid Whole-Body Control
Accepted as an oral paper at CoRL 2026, the SuperMimic framework uses a differentiable world model to train humanoid whole-body control on a single GPU in three hours, outperforming previous methods that required massive GPU clusters.
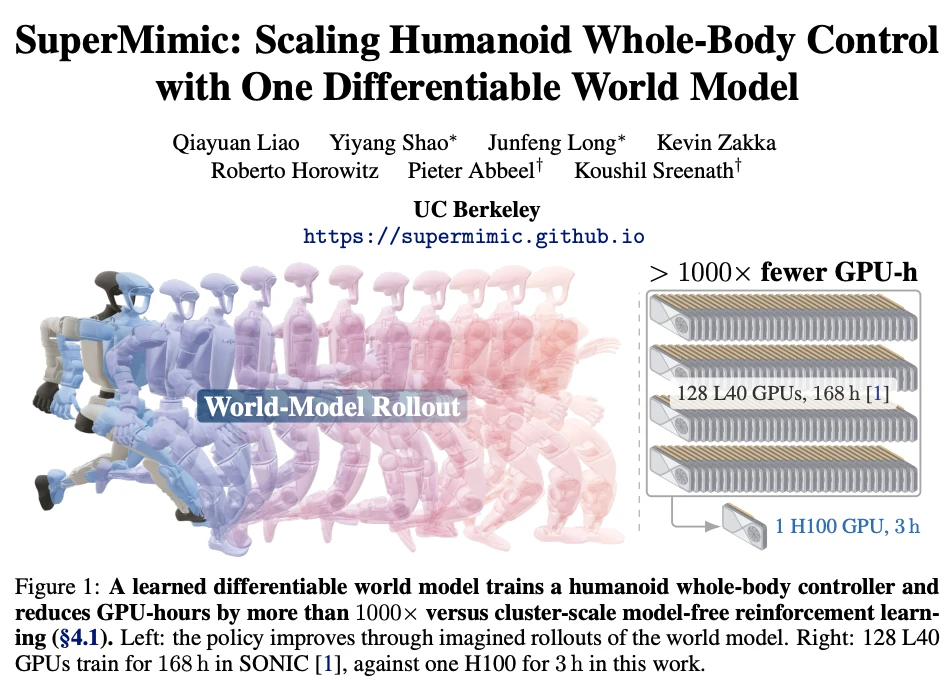
UC Berkeley's SuperMimic Trains Humanoid Whole-Body Control on a Single GPU in 3 Hours, Surpassing 128-GPU Baseline
A UC Berkeley team introduced SuperMimic, a framework that uses a single differentiable world model to scale humanoid whole-body control. The approach trains on a single NVIDIA H100 GPU in 3 hours to outperform the SONIC baseline, which required 128 NVIDIA L40 GPUs over 7 days, reducing GPU-hour costs by more than 1,000 times.
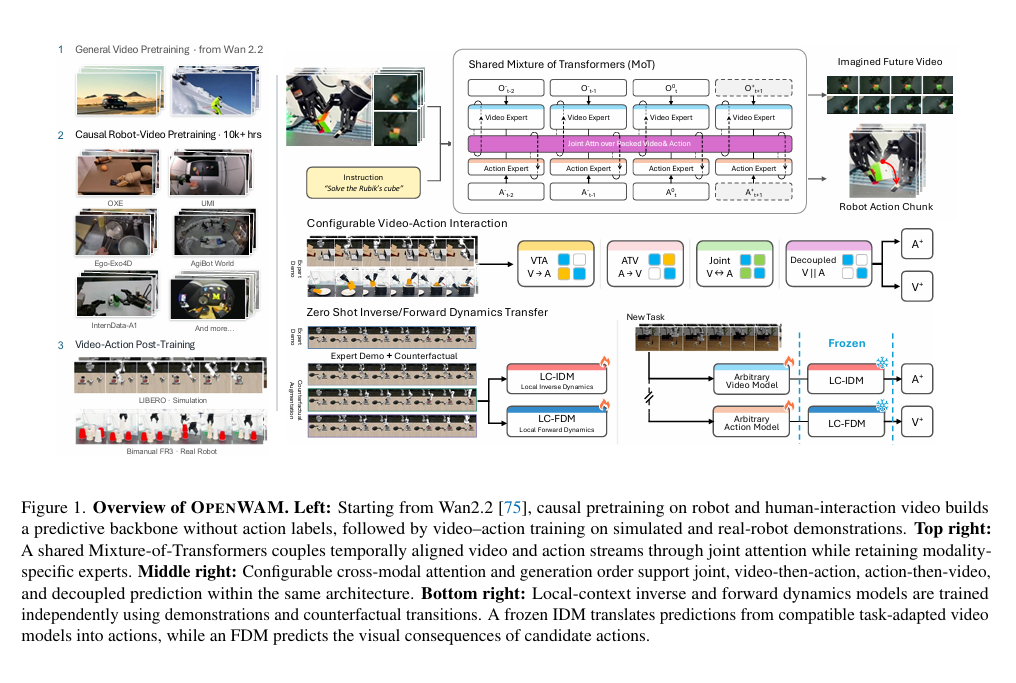
Institute of Automation, Chinese Academy of Sciences and Amap Introduce DreamTrue, an Action-Faithful Robot World Model for Future Video Prediction
Researchers from the Institute of Automation, Chinese Academy of Sciences and Amap introduce DreamTrue, a robot world model that renders actions as visual conditions to predict both successful and failed outcomes. The method uses counterfactual post-training to address missing failure demonstrations, and the article reports interaction defect rates on AgiBot platforms falling from 48.12% to 6.25%.
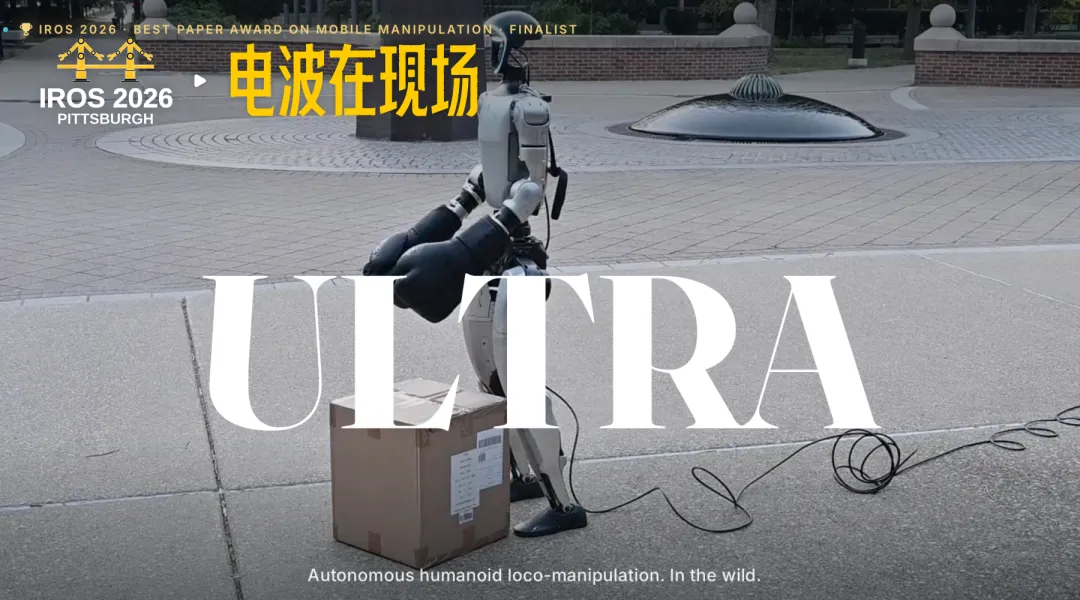
ULTRA: Toward Autonomous Whole-Body Movement and Manipulation
At IROS 2026, Xialin He and Sirui Xu from UIUC presented ULTRA, a unified multimodal control framework that enables humanoid robots to learn whole-body loco-manipulation through physical simulation and reinforcement learning.