

Embodied AIActionRobotFutureThinkWorldTrainingExperience RetrievalMultimodal EmbeddingIn-Context Learning
Robotics Learning
3 related stories
NVIDIA Proposes ThinkWorld to Train VLAs on Unannotated Human Videos via Chain-of-Dynamics and Imagined Futures
NVIDIA and KAIST introduce ThinkWorld, a vision-language action framework that leverages chain-of-dynamics reasoning and imagined future states to extract training signals from unannotated human videos for robot policy learning.
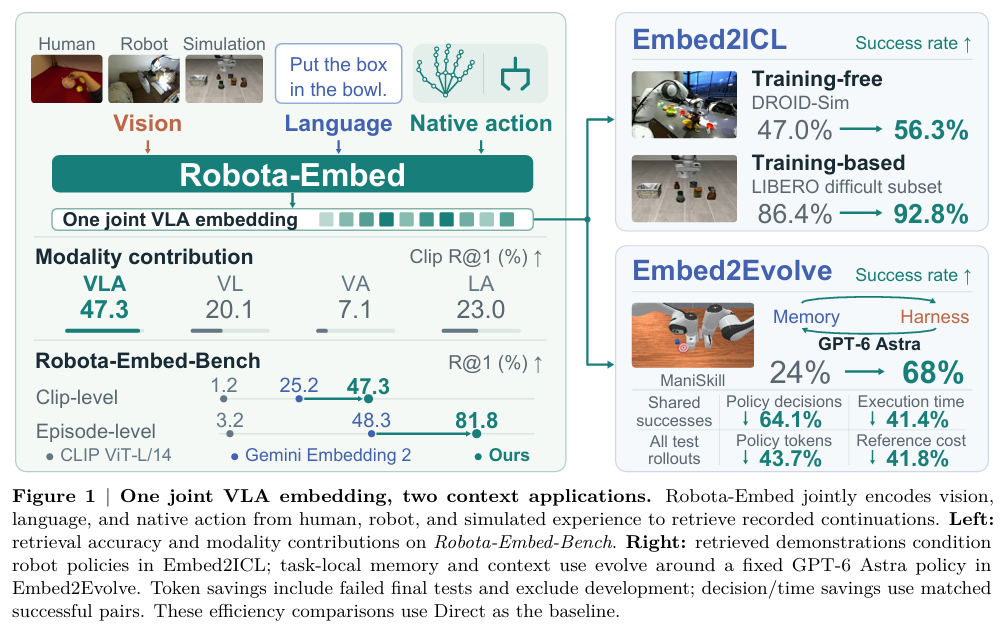
Robota-Embed: Joint Action and Visual Encoding for Robot In-Context Learning
A joint team from NVIDIA, MIT, UC Berkeley, Oxford, and CMU introduces Robota-Embed, a unified VLA embedding that incorporates action data into experience retrieval. The model significantly improves robot in-context learning by matching future behavior logic rather than just visual similarity.
π*0.6 VLA Model May Enable Fully Autonomous Coffee Shops
Physical Intelligence (PI) released the π*0.6 model, using a novel 'Recap' training method to help Visual-Language-Action (VLA) models break through imitation learning bottlenecks.