

Vision-Language-Action Model
4 related stories
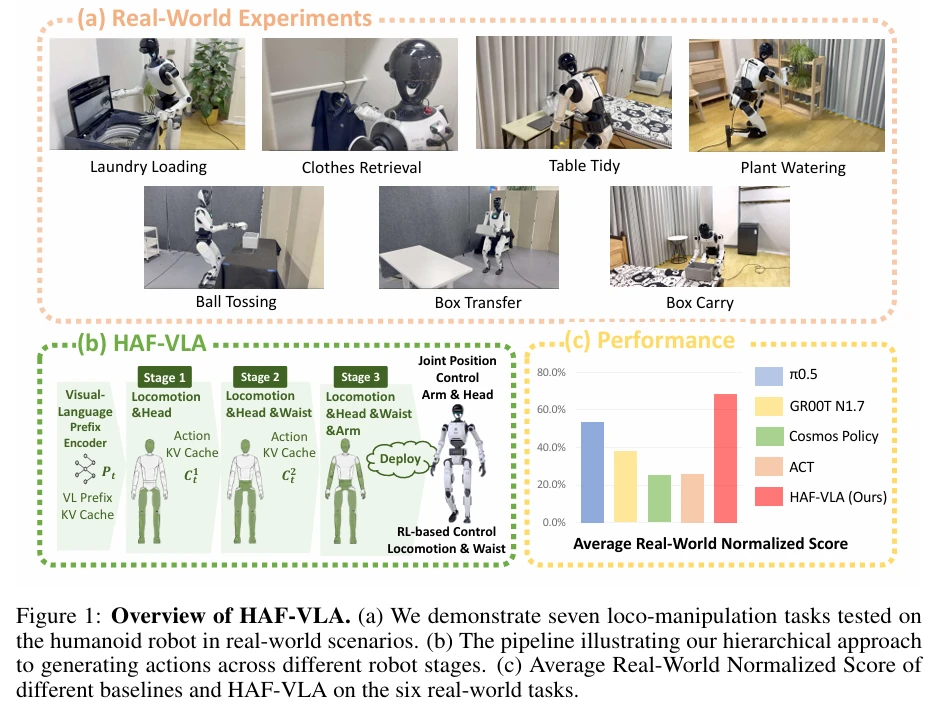
HAF-VLA Enables Hierarchical Generation of Coordinated Full-Body Actions in Humanoid Robots
A joint team from Peking University, Tsinghua University, and other institutions has proposed HAF-VLA, a hierarchical framework that enables humanoid robots to generate coordinated full-body actions by sequentially planning movements along the kinematic chain to avoid compensatory instability.
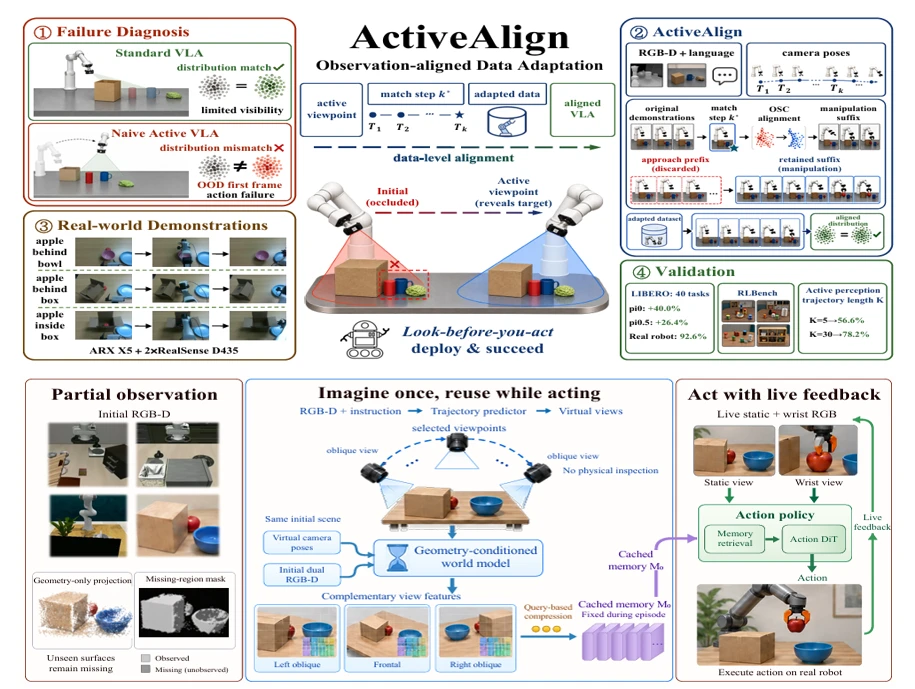
Fudan Team Bridges Active Perception and Vision-Language-Action Models to Overcome Viewpoint Shifts
Two papers from Fudan University introduce ActiveAlign and AWAM, which align training data and representations with active camera movements to prevent distribution shifts in vision-language-action models when robots adjust their viewpoints to overcome occlusions.

Samsung Researchers Show Compressed VLA Model Outperforms Larger Teacher on Real Robots
Researchers from Samsung R&D Institute demonstrate that compressing a visual-language-action model's Transformer layers from 18 to 6 via knowledge distillation reduces inference latency by more than half while maintaining success rates, enabling faster real-world robotic deployment.
Track4Action: Distilling 3D World Dynamics Into VLA Policies for Robust Robot Control
A new approach by Shanghai Jiao Tong University and Zhejiang University integrates 3D world tracking knowledge into Vision-Language-Action models to help robots understand how their actions change the physical environment.