

Latest
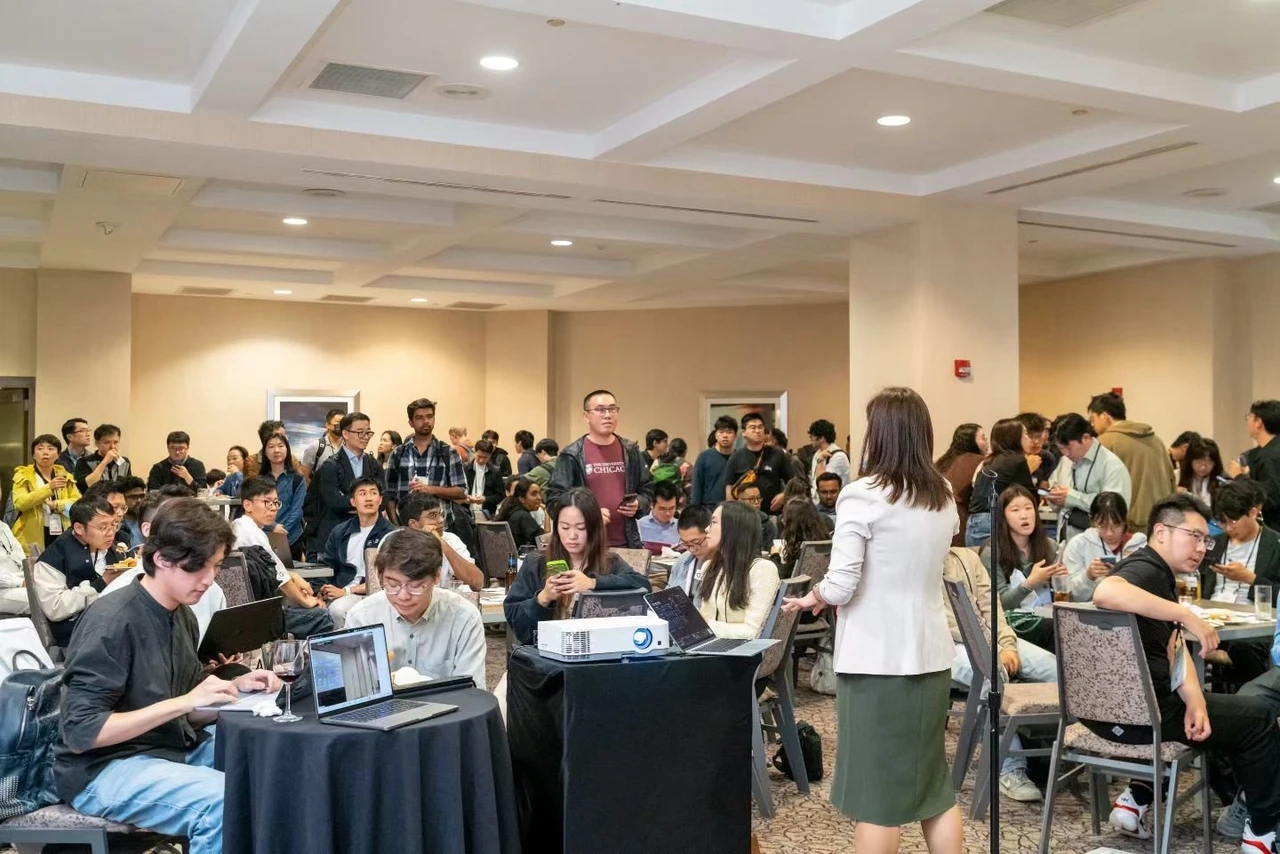
In Conversation with Saturday Robotics Founder Junfan Zhu: “By the Time a Robotics Paper Is Published, Its Approach May Already Be Out of Date”
How Junfan Zhu is building a cross-disciplinary robotics research community in the Bay Area while working on better ways to evaluate AI systems in the physical world, and why he thinks robotics has yet to have its benchmark moment.
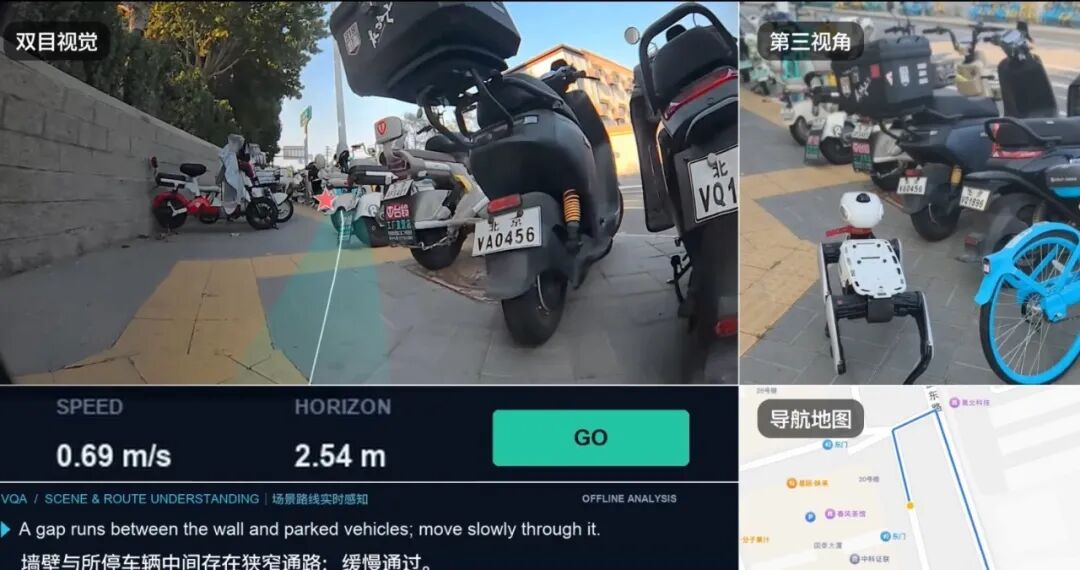
Robots Can Run Marathons, So Why Is It Still So Hard to Reach the Front Desk?
Vita Dynamics introduces VbotNav-0, an asynchronous cloud-edge navigation framework that enables robots to seamlessly transition from outdoor streets to indoor environments using unified route tokens and a three-tier decision architecture.
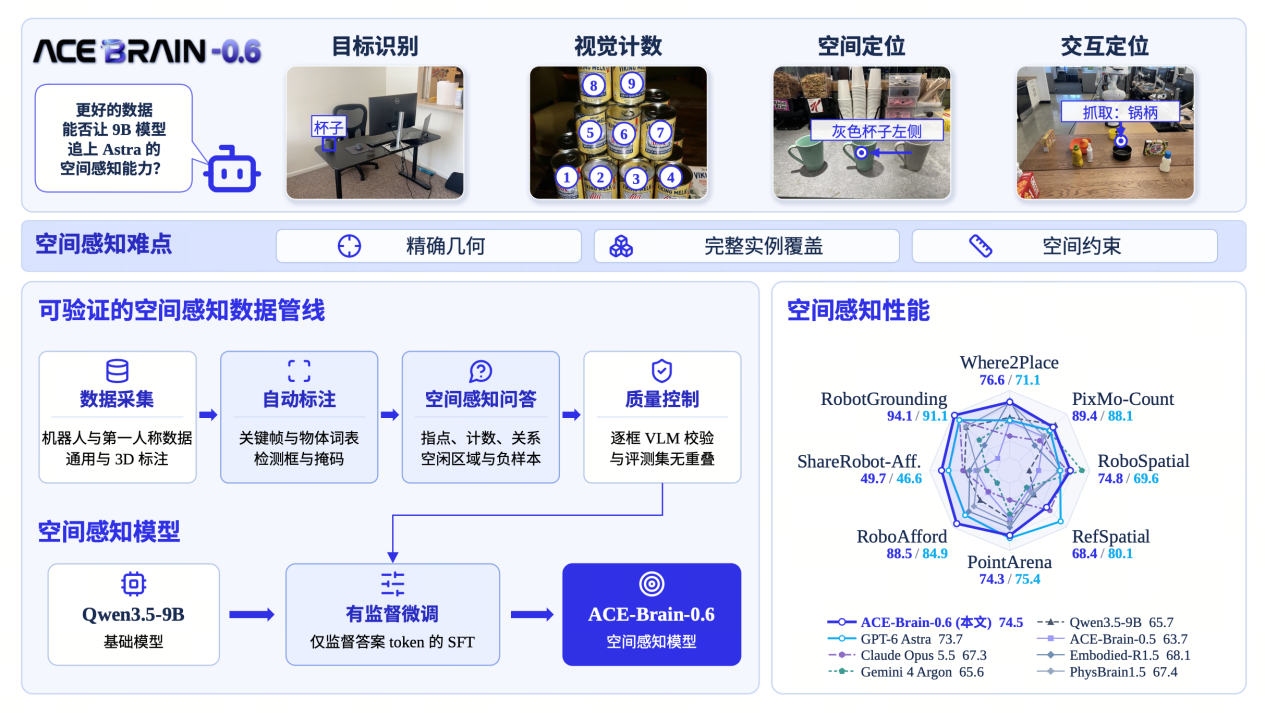
ACE Robotics Releases ACE-Brain-0.6, Outperforming GPT-6 Astra in Six Spatial Anchoring Tests
ACE Robotics has released the 9B embodied AI model ACE-Brain-0.6, which scored higher than GPT-6 Astra in six of eight visual spatial anchoring benchmarks. The team attributes performance gains to data expansion from 260,000 to approximately one million training samples.
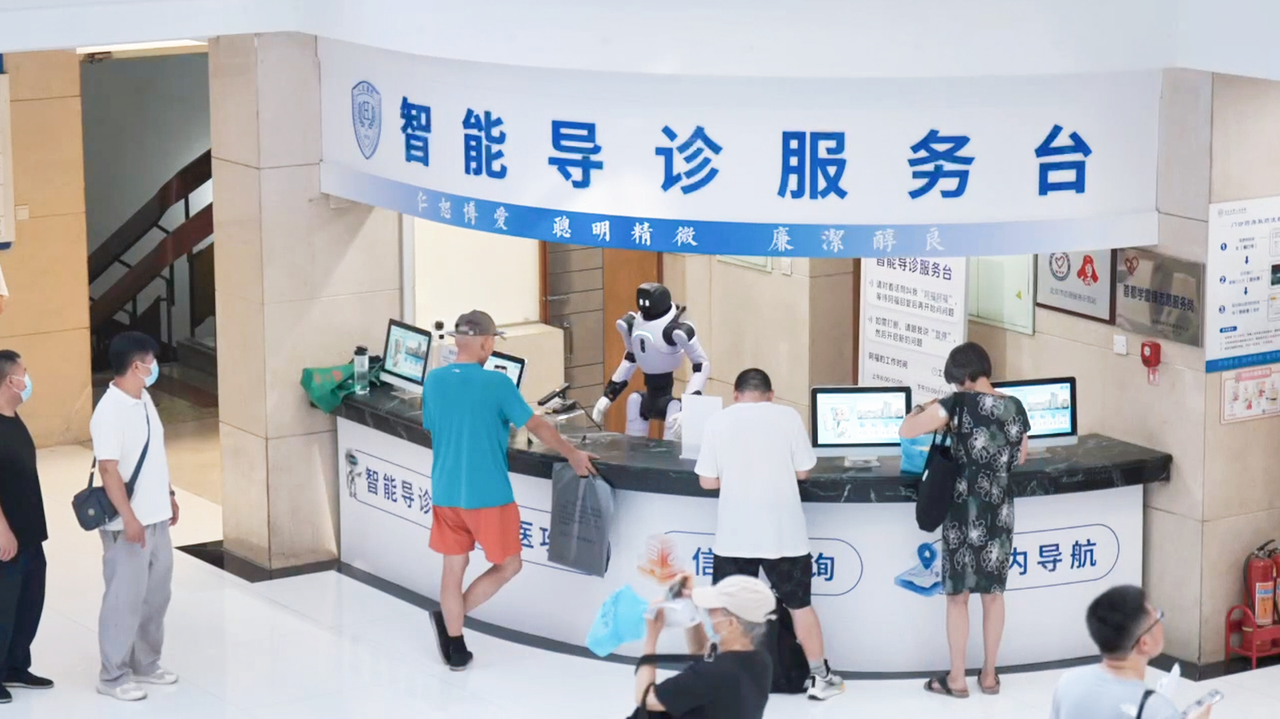
AGIBOT X2 Provides Patient Guidance at Peking University People's Hospital, Logging Over 46,000 Interactions
AgiBot's patient guidance project with Ant A-Fu is operating at Peking University People's Hospital. By September 30, AGIBOT X2 had completed 46,686 interactions over 66 working days.
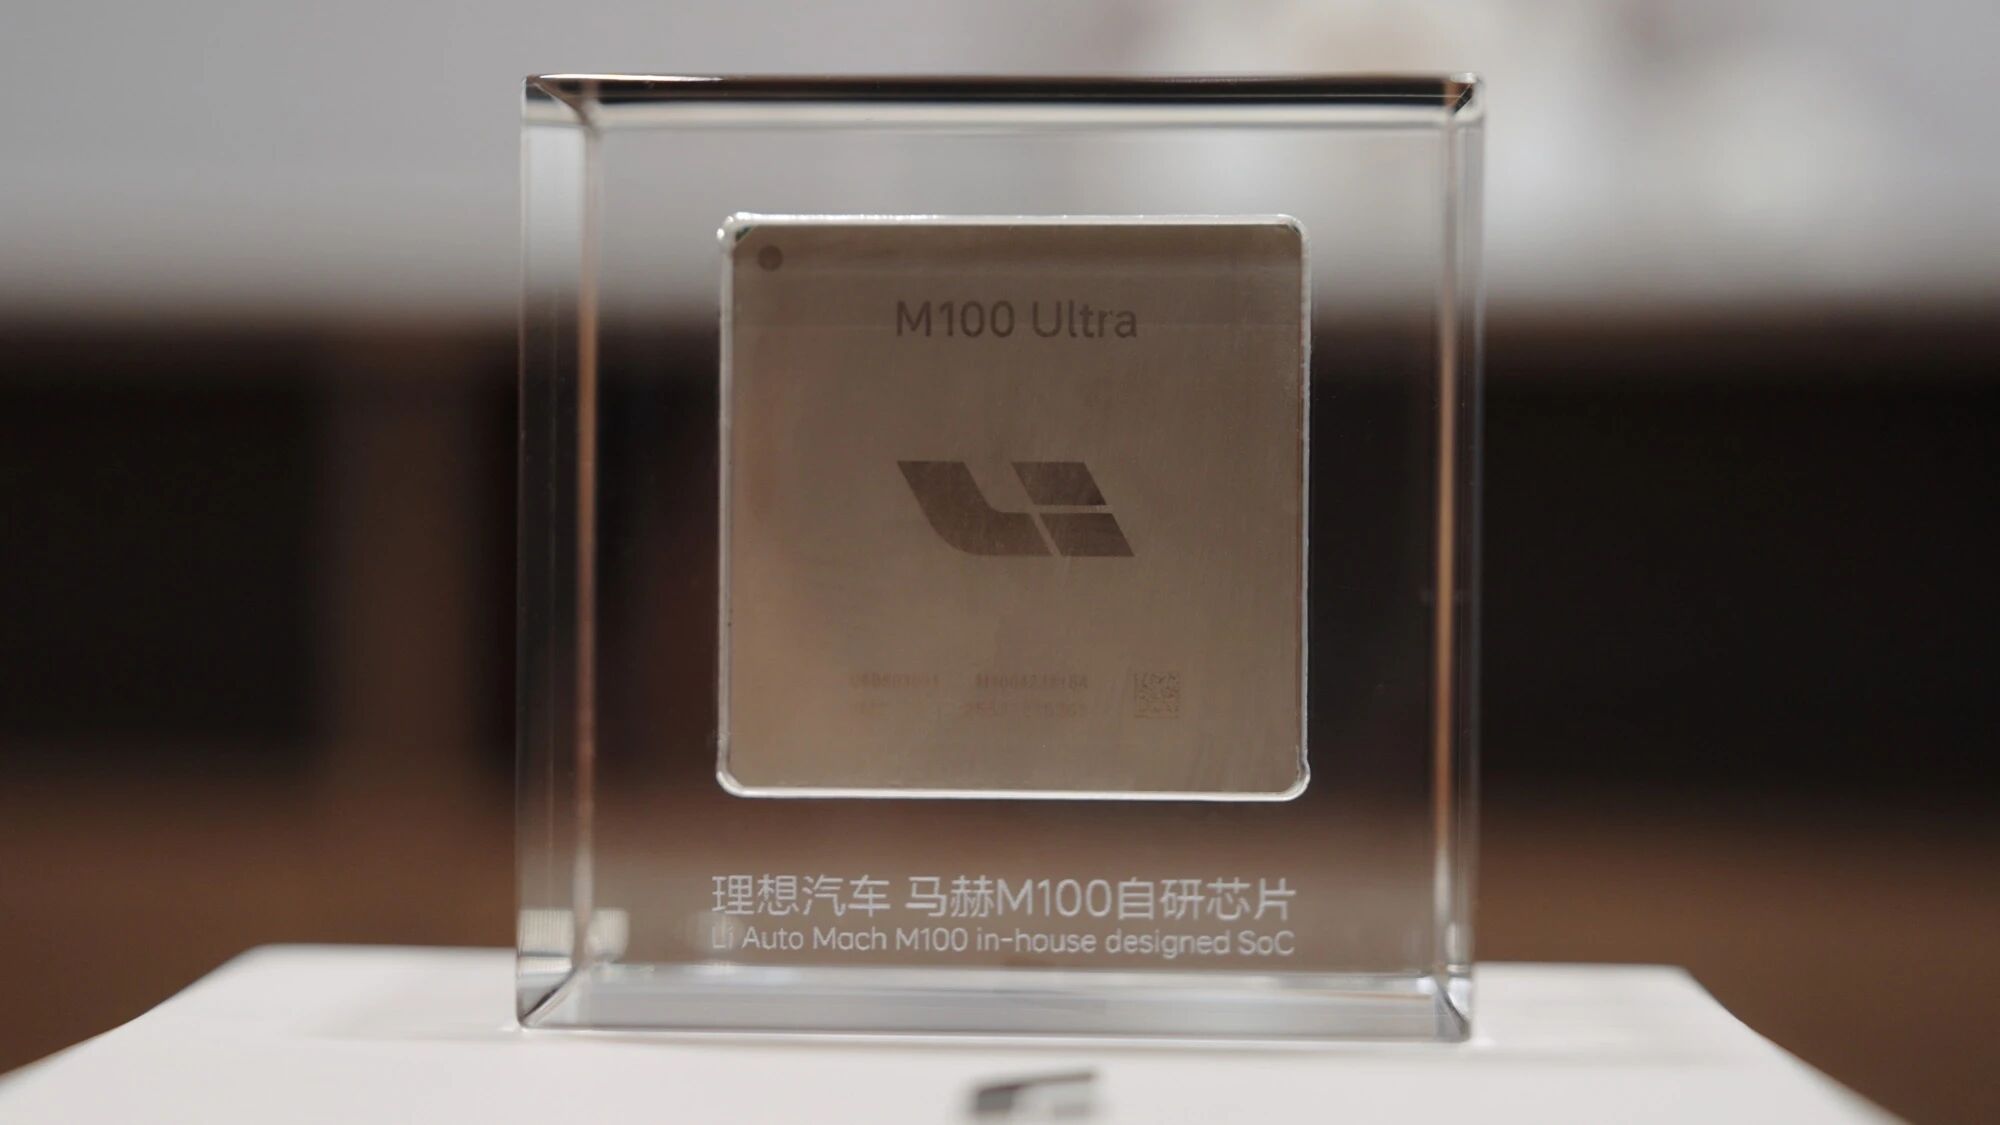
Li Auto's Chip Unit MHX Technology Signs RMB 1.625 Billion Financing Deal to Expand Beyond Automotive
Shanghai Mahe Xin Technology Co., Ltd., a chip subsidiary of Li Auto, has signed its first-round equity financing agreement worth RMB 1.625 billion. The deal aims to support the external supply of chips and domain controllers, targeting non-automotive markets.

NVIDIA and Semiconductor Leaders Use CUDA-X Libraries to Advance AI-Defined Fabs
At SEMICON West 2026, NVIDIA announced that leading semiconductor companies are adopting its CUDA-X libraries, including the new cuPotential, to build AI agents for atomic simulation and digital twin modeling. These tools aim to optimize manufacturing processes and improve efficiency in the development of AI-defined fabs.
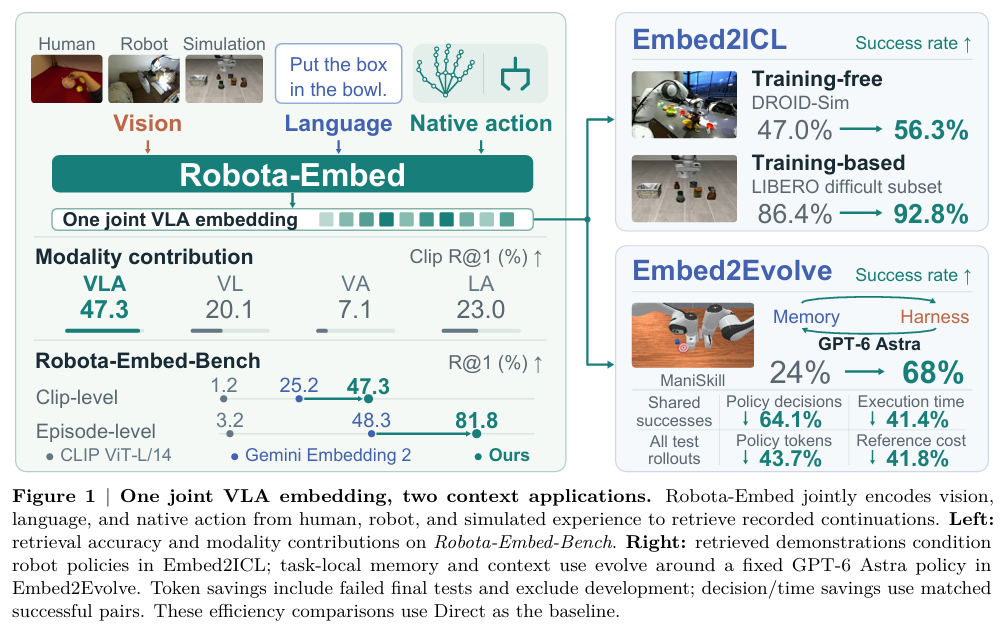
Robota-Embed: Joint Action and Visual Encoding for Robot In-Context Learning
A joint team from NVIDIA, MIT, UC Berkeley, Oxford, and CMU introduces Robota-Embed, a unified VLA embedding that incorporates action data into experience retrieval. The model significantly improves robot in-context learning by matching future behavior logic rather than just visual similarity.
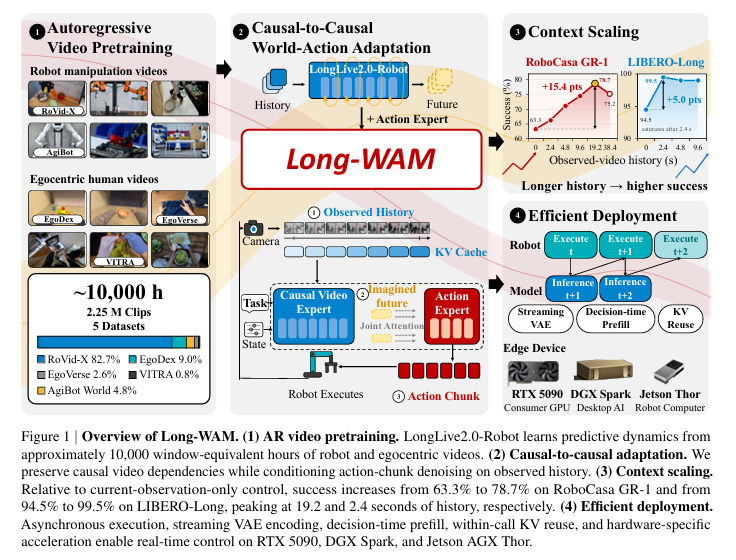
NVIDIA and MIT Researchers Show Long-Context Robotics Requires Autoregressive World Models
A joint paper from NVIDIA, MIT, HKU and UCSD demonstrates that simply extending visual history does not improve robot control; the model must first learn autoregressive prediction to effectively use long contexts. On the RoboCasa GR-1 platform, task success rates rose from 63.3% to 78.7% when context was extended to 19.2 seconds.
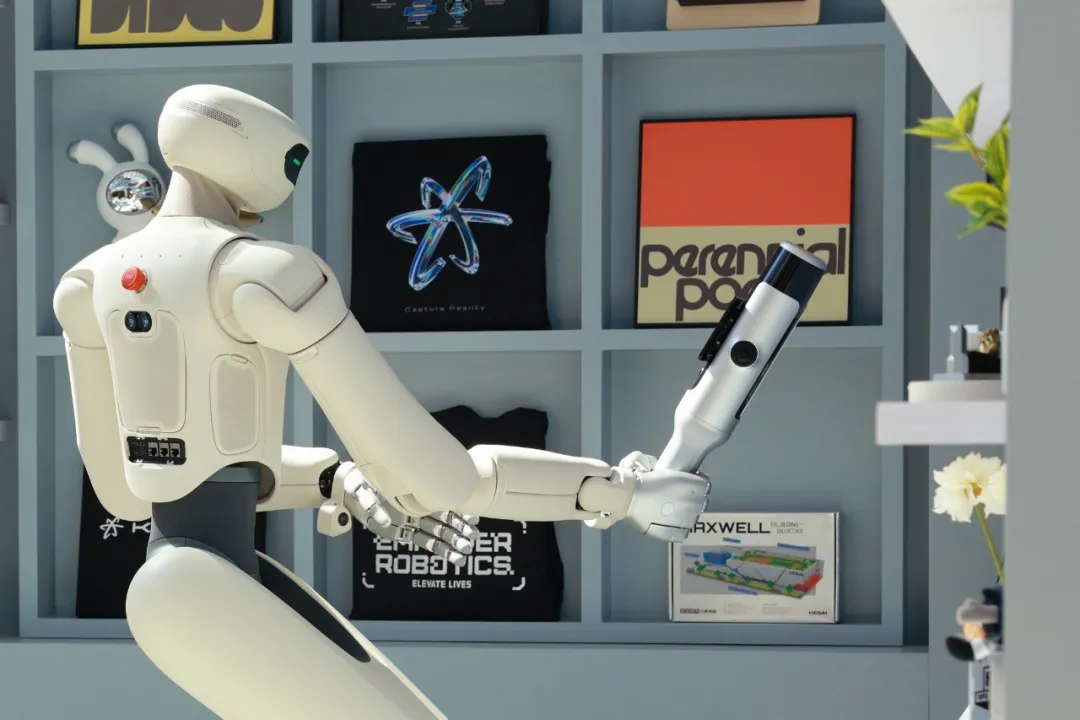
Hesai Launches AI Camera Kosmo to Monetize the Real World as Data
Hesai launched the Kosmo One handheld scanner and Kosmo World platform, enabling robot companies like Sharpa to build high-fidelity simulation environments from real-world scans. The move signals a shift from selling sensors to providing 3D data assets and cloud processing services.
PrimeBot’s Hao Dong: Lowering Post-Training Costs for Home Robots
At IROS 2026, PrimeBot and Peking University hosted a dual-arm manipulation challenge. Chief Scientist Hao Dong discusses how post-training improves reliability in home environments and introduces HIL-UMI to lower data collection costs.
I-BFM: Unsupervised Reinforcement Learning Enables Robust Humanoid Interaction After Falls
Researchers from Tongji University and Tsinghua University introduce I-BFM, a behavior foundation model that uses forward-backward representation to allow humanoid robots to recover from falls and adapt to disturbances without re-planning trajectories.
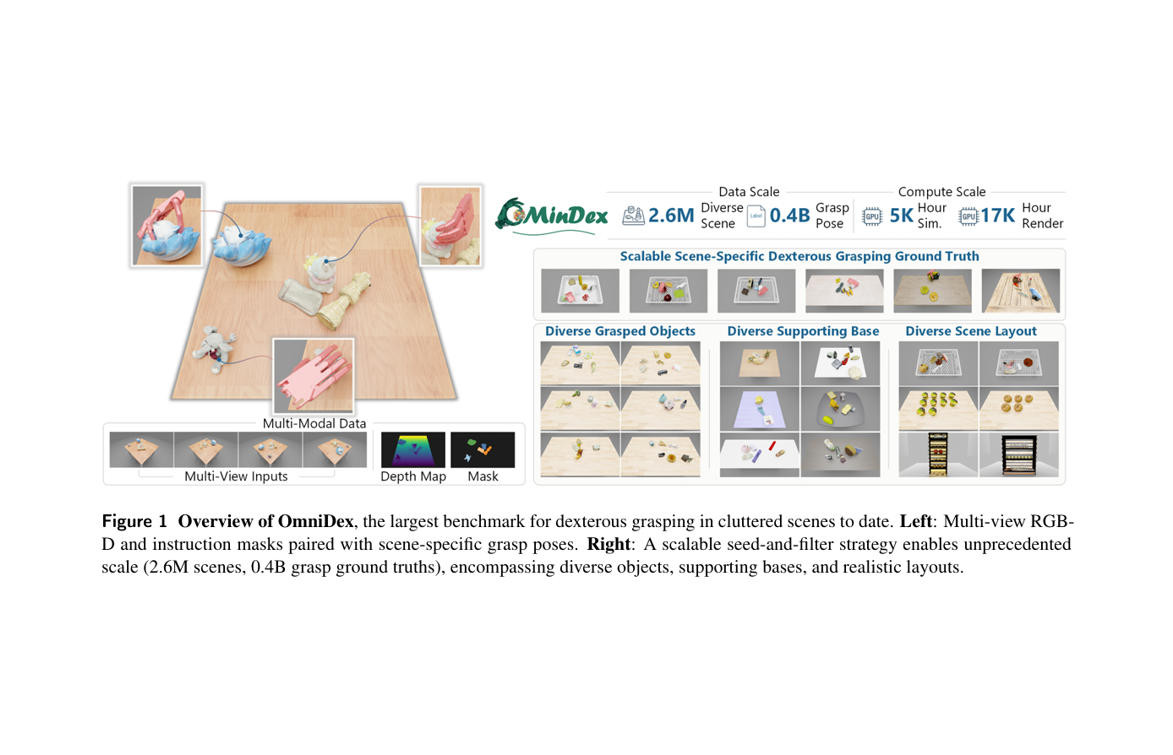
OmniDex Dataset Scales Dexterous Grasping to 2.6 Million Cluttered Scenes
A team led by Xiaogang Wang and Hongsheng Li publishes OmniDex, a dataset of 2.6 million cluttered scenes and 400 million grasp annotations for dexterous hands, using offline pre-computation and soft winner-take-all learning to enable high-precision grasping without post-inference optimization.