

Embodied AI
164 related stories
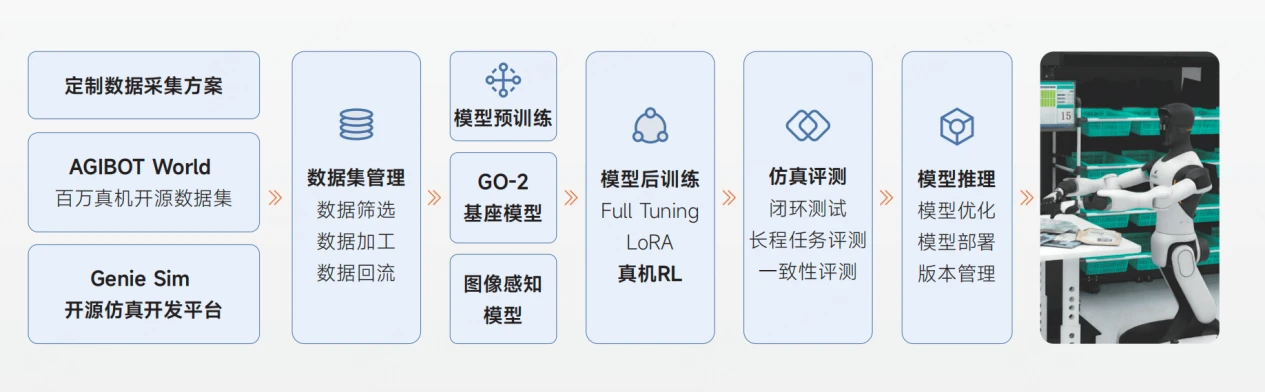
AgiBot Launches Genie Studio 2.0 to Validate Robot Deployment in New Scenarios in as Few as 7 Days
On October 23, AgiBot released Genie Studio 2.0, an all-in-one embodied AI operations platform and the second installment of its "AI WAVE" series. The platform comprises Flywheel, Agent, and Monitor modules, covering data collection, model training, simulation testing, task orchestration, and multi-robot operations.
UC Berkeley's SuperMimic Slashes Compute for Humanoid Whole-Body Control
Accepted as an oral paper at CoRL 2026, the SuperMimic framework uses a differentiable world model to train humanoid whole-body control on a single GPU in three hours, outperforming previous methods that required massive GPU clusters.
Beyond the Hardware Sale: Can Robot Integrators Turn a Profit?
While robot manufacturers focus on hardware sales, system integrators are tasked with making these machines actually work on the factory floor. However, turning a profit from this secondary development is proving difficult, with a single palletizing project requiring over RMB 1 million in combined hardware and software investment.
 1:52
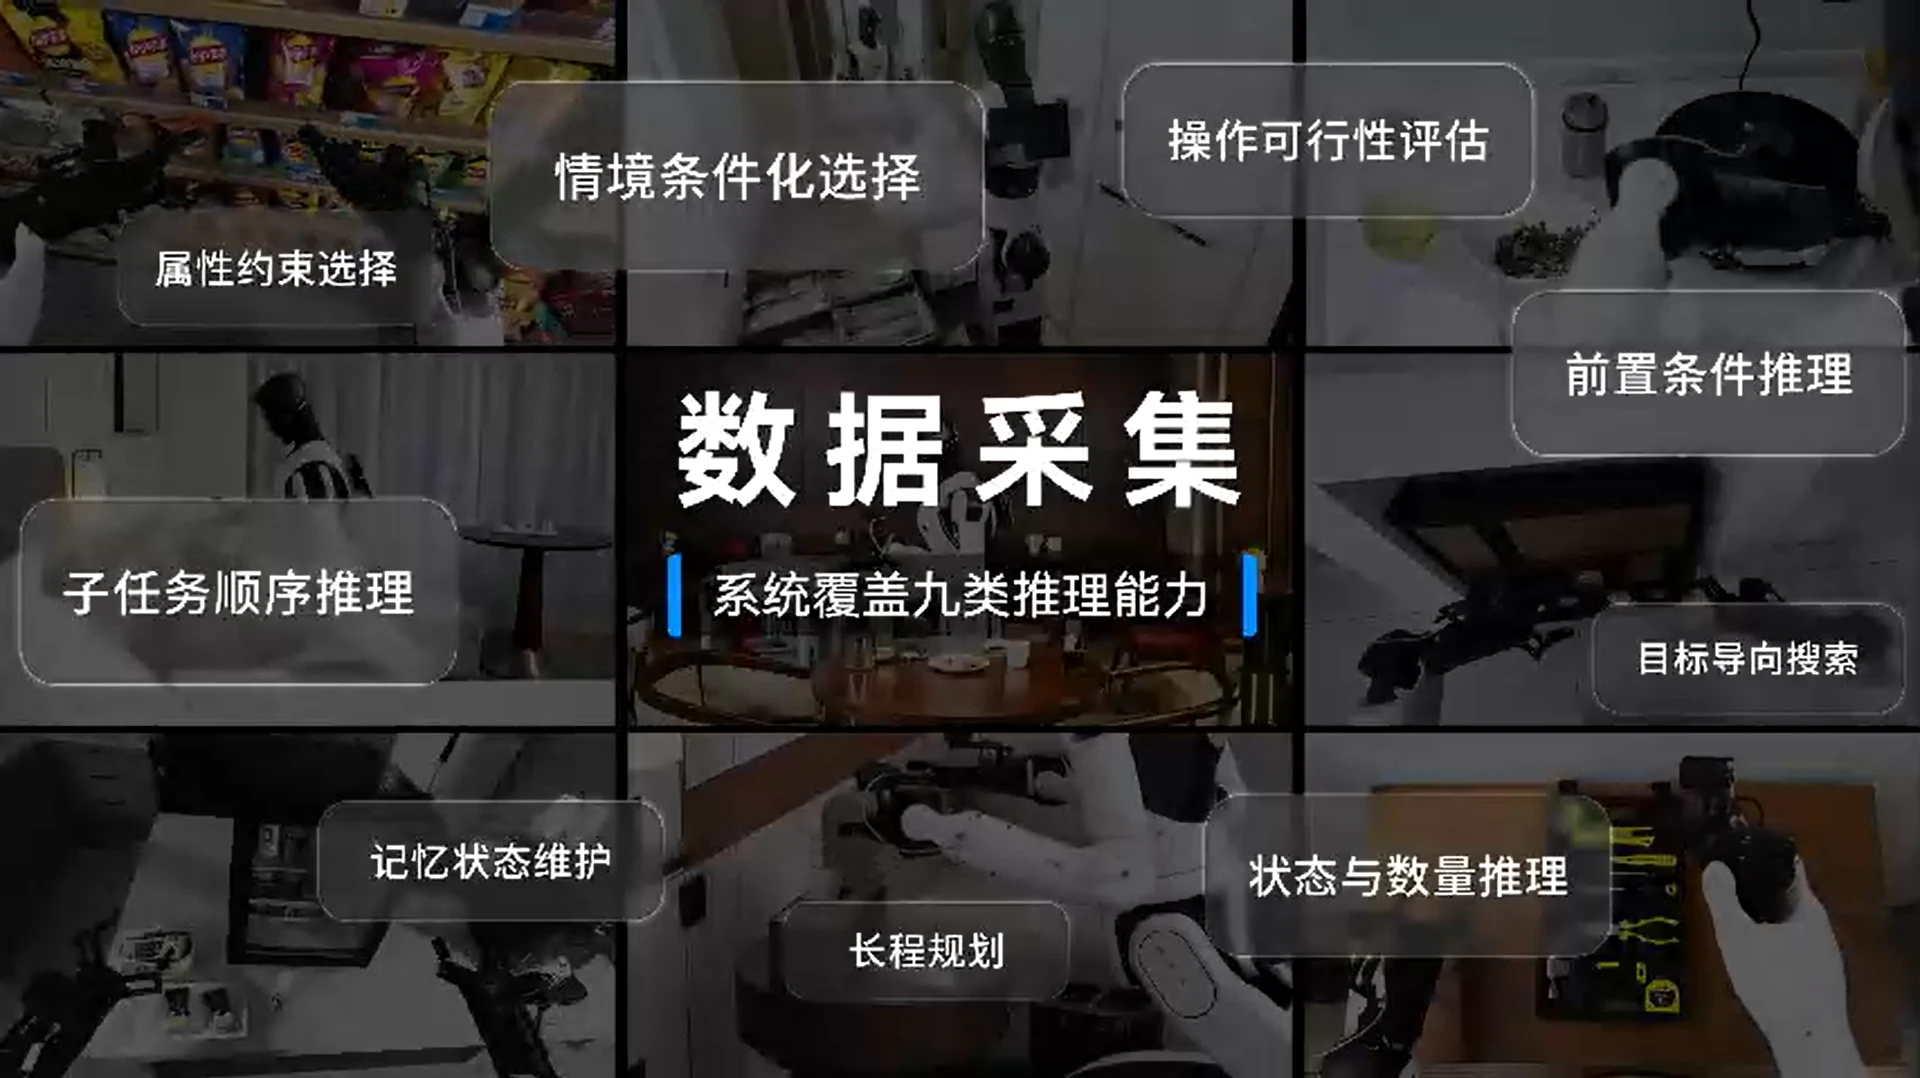
AgiBot Open-Sources AGIBOT WORLD 2026 Embodied Reasoning Dataset Covering Nine Scenarios
On October 22, AgiBot open-sourced the fourth installment of the AGIBOT WORLD 2026 dataset, focusing on embodied reasoning as the first release in its AI WAVE series. The dataset covers nine logical reasoning scenarios and provides both high-level question answering and low-level action trajectories, enabling robots to make decisions and execute operations based on task goals, environmental conditions, and execution history.
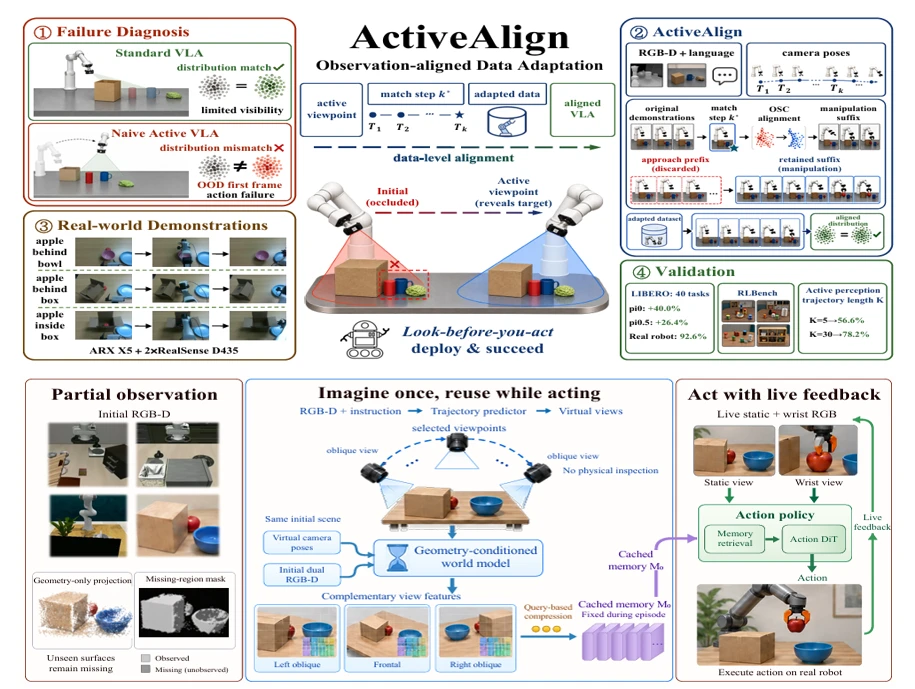
Fudan Team Bridges Active Perception and Vision-Language-Action Models to Overcome Viewpoint Shifts
Two papers from Fudan University introduce ActiveAlign and AWAM, which align training data and representations with active camera movements to prevent distribution shifts in vision-language-action models when robots adjust their viewpoints to overcome occlusions.
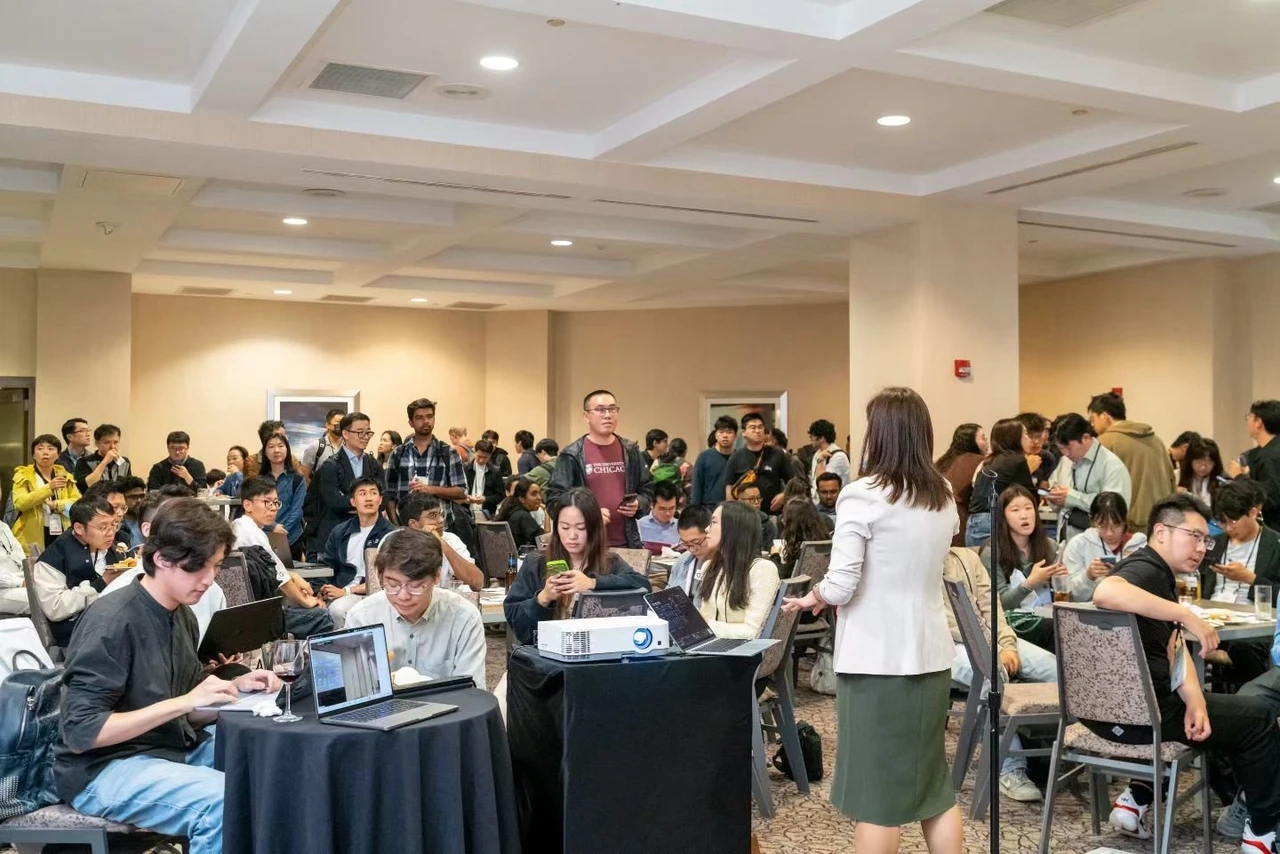
In Conversation with Saturday Robotics Founder Junfan Zhu: “By the Time a Robotics Paper Is Published, Its Approach May Already Be Out of Date”
How Junfan Zhu is building a cross-disciplinary robotics research community in the Bay Area while working on better ways to evaluate AI systems in the physical world, and why he thinks robotics has yet to have its benchmark moment.
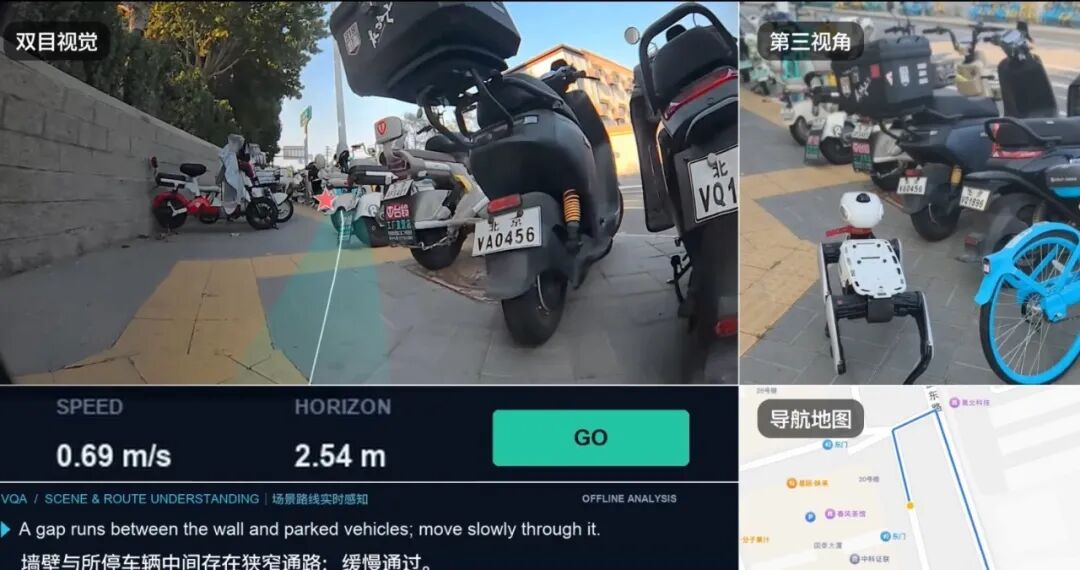
Robots Can Run Marathons, So Why Is It Still So Hard to Reach the Front Desk?
Vita Dynamics introduces VbotNav-0, an asynchronous cloud-edge navigation framework that enables robots to seamlessly transition from outdoor streets to indoor environments using unified route tokens and a three-tier decision architecture.
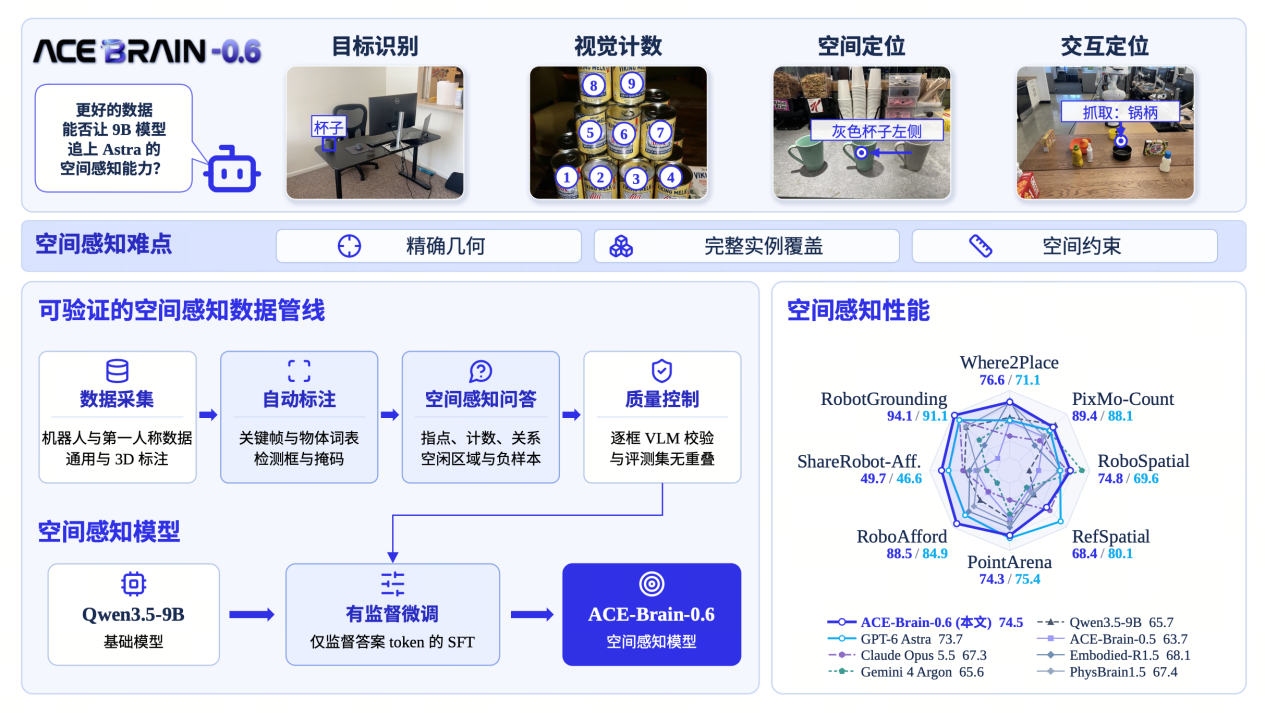
ACE Robotics Releases ACE-Brain-0.6, Outperforming GPT-6 Astra in Six Spatial Anchoring Tests
ACE Robotics has released the 9B embodied AI model ACE-Brain-0.6, which scored higher than GPT-6 Astra in six of eight visual spatial anchoring benchmarks. The team attributes performance gains to data expansion from 260,000 to approximately one million training samples.
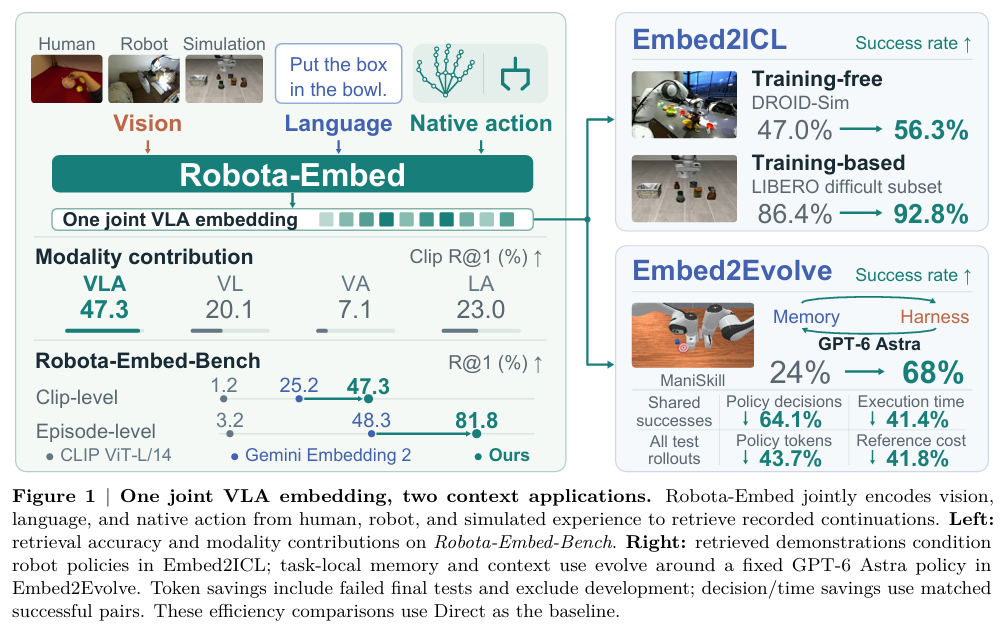
Robota-Embed: Joint Action and Visual Encoding for Robot In-Context Learning
A joint team from NVIDIA, MIT, UC Berkeley, Oxford, and CMU introduces Robota-Embed, a unified VLA embedding that incorporates action data into experience retrieval. The model significantly improves robot in-context learning by matching future behavior logic rather than just visual similarity.
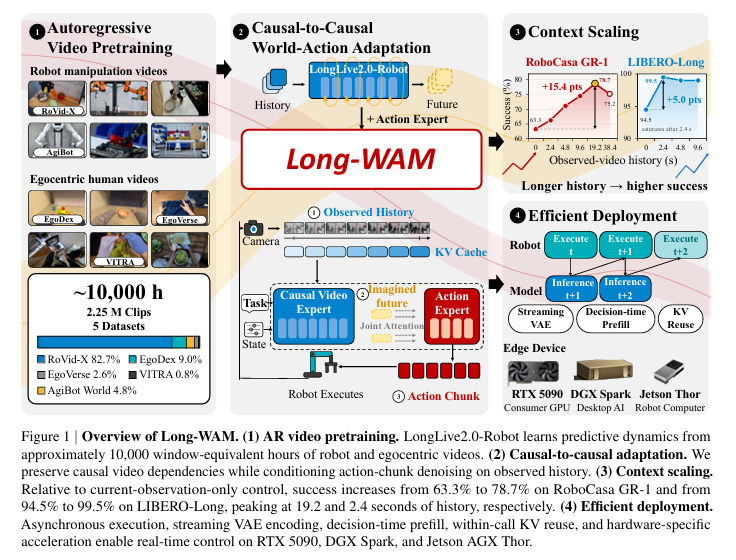
NVIDIA and MIT Researchers Show Long-Context Robotics Requires Autoregressive World Models
A joint paper from NVIDIA, MIT, HKU and UCSD demonstrates that simply extending visual history does not improve robot control; the model must first learn autoregressive prediction to effectively use long contexts. On the RoboCasa GR-1 platform, task success rates rose from 63.3% to 78.7% when context was extended to 19.2 seconds.
PrimeBot’s Hao Dong: Lowering Post-Training Costs for Home Robots
At IROS 2026, PrimeBot and Peking University hosted a dual-arm manipulation challenge. Chief Scientist Hao Dong discusses how post-training improves reliability in home environments and introduces HIL-UMI to lower data collection costs.
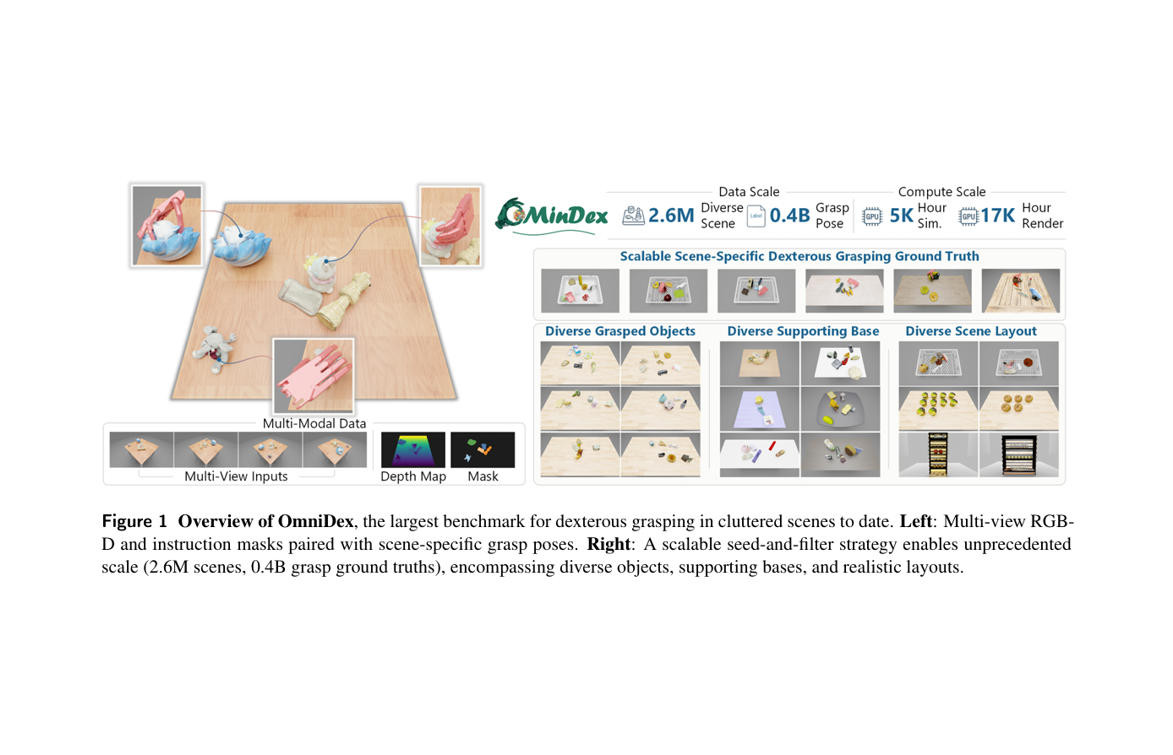
OmniDex Dataset Scales Dexterous Grasping to 2.6 Million Cluttered Scenes
A team led by Xiaogang Wang and Hongsheng Li publishes OmniDex, a dataset of 2.6 million cluttered scenes and 400 million grasp annotations for dexterous hands, using offline pre-computation and soft winner-take-all learning to enable high-precision grasping without post-inference optimization.